Чем отличается master и origin master
Branching in Git is one of its many great features. If you have used other version control systems, it’s probably helpful to forget most of what you think about branches — in fact, it may be more helpful to think of them practically as contexts since that is how you will most often be using them. When you checkout different branches, you change contexts that you are working in and you can quickly context-switch back and forth between several different branches.
In a nutshell you can create a branch with git branch (branchname) , switch into that context with git checkout (branchname) , record commit snapshots while in that context, then can switch back and forth easily. When you switch branches, Git replaces your working directory with the snapshot of the latest commit on that branch so you don’t have to have multiple directories for multiple branches. You merge branches together with git merge . You can easily merge multiple times from the same branch over time, or alternately you can choose to delete a branch immediately after merging it.
docs book git branch list, create and manage working contexts
docs book git checkout switch to a new branch context
The git branch command is a general branch management tool for Git and can do several different things. We’ll cover the basic ones that you’ll use most — listing branches, creating branches and deleting branches. We will also cover basic git checkout here which switches you between your branches.
git branch list your available branches
Without arguments, git branch will list out the local branches that you have. The branch that you are currently working on will have a star next to it and if you have coloring turned on, will show the current branch in green.
This means that we have a ‘master’ branch and we are currently on it. When you run git init it will automatically create a ‘master’ branch for you by default, however there is nothing special about the name — you don’t actually have to have a ‘master’ branch but since it’s the default that is created, most projects do.
git branch (branchname) create a new branch
So let’s start by creating a new branch and switching to it. You can do that by running git branch (branchname) .
Now we can see that we have a new branch. When you create a branch this way it creates the branch at your last commit so if you record some commits at this point and then switch to ‘testing’, it will revert your working directory context back to when you created the branch in the first place — you can think of it like a bookmark for where you currently are. Let’s see this in action — we use git checkout (branch) to switch the branch we’re currently on.
So now we can see that when we switch to the ‘testing’ branch, our new files were removed. We could switch back to the ‘master’ branch and see them re-appear.
git branch -v see the last commit on each branch
If we want to see last commits on each branch we can run git branch -v to see them.
git checkout -b (branchname) create and immediately switch to a branch
In most cases you will be wanting to switch to the branch immediately, so you can do work in it and then merging into a branch that only contains stable work (such as ‘master’) at a later point when the work in your new context branch is stable. You can do this pretty easily with git branch newbranch; git checkout newbranch , but Git gives you a shortcut for this: git checkout -b newbranch .
You can see there how we created a branch, removed some of our files while in the context of that branch, then switched back to our main branch and we see the files return. Branching safely isolates work that we do into contexts we can switch between.
If you start on work it is very useful to always start it in a branch (because it’s fast and easy to do) and then merge it in and delete the branch when you’re done. That way if what you’re working on doesn’t work out you can easily discard it and if you’re forced to switch back to a more stable context your work in progress is easy to put aside and then come back to.
git branch -d (branchname) delete a branch
If we want to delete a branch (such as the ‘testing’ branch in the previous example, since there is no unique work on it), we can run git branch -d (branch) to remove it.
git push (remote-name) :(branchname) delete a remote branch
When you’re done with a remote branch, whether it’s been merged into the remote master or you want to abandon it and sweep it under the rug, you’ll issue a git push command with a specially placed colon symbol to remove that branch.
In the above example you’ve deleted the «tidy-cutlery» branch of the «origin» remote. A way to remember this is to think of the git push remote-name local-branch:remote-branch syntax. This states that you want to push your local branch to match that of the remote. When you remove the local-branch portion you’re now matching nothing to the remote, effectively telling the remote branch to become nothing.
Alternatively, you can run git push remote-name —delete branchname which is a wrapper for the colon refspec (a source:destination pair) of deleting a remote branch.
In a nutshell you use git branch to list your current branches, create new branches and delete unnecessary or already merged branches.
docs book git merge merge a branch context into your current one
Once you have work isolated in a branch, you will eventually want to incorporate it into your main branch. You can merge any branch into your current branch with the git merge command. Let’s take as a simple example the ‘removals’ branch from above. If we create a branch and remove files in it and commit our removals to that branch, it is isolated from our main (‘master’, in this case) branch. To include those deletions in your ‘master’ branch, you can just merge in the ‘removals’ branch.
more complex merges
Of course, this doesn’t just work for simple file additions and deletions. Git will merge file modifications as well — in fact, it’s very good at it. For example, let’s see what happens when we edit a file in one branch and in another branch we rename it and then edit it and then merge these branches together. Chaos, you say? Let’s see.
So first we’re going to create a new branch named ‘change_class’ and switch to it so your class renaming changes are isolated. We’re going to change each instance of ‘HelloWorld’ to ‘HiWorld’.
So now we’ve committed the class renaming changes to the ‘change_class’ branch. To switch back to the ‘master’ branch the class name will revert to what it was before we switched branches. Here we can change something different (in this case the printed output) and at the same time rename the file from hello.rb to ruby.rb .
Now those changes are recorded in the ‘master’ branch. Notice that the class name is back to ‘HelloWorld’, not ‘HiWorld’. To incorporate the ‘HiWorld’ change we can just merge in the ‘change_class’ branch. However, the name of the file has changed since we branched, what will Git do?
Well, it will just figure it out. Notice that there are no merge conflicts and the file that had been renamed now has the ‘HiWorld’ class name change that was done in the other branch. Pretty cool.
merge conflicts
So, Git merges are magical, we never ever have to deal with merge conflicts again, right? Not quite. In situations where the same block of code is edited in different branches there is no way for a computer to figure it out, so it’s up to us. Let’s see another example of changing the same line in two branches.
Now we have committed a change to one line in our README file in a branch. Now let’s change the same line in a different way back on our ‘master’ branch.
Now is the fun part — we will merge the first branch into our master branch, causing a merge conflict.
You can see that Git inserts standard merge conflict markers, much like Subversion, into files when it gets a merge conflict. Now it’s up to us to resolve them. We will do it manually here, but check out git mergetool if you want Git to fire up a graphical mergetool (like kdiff3, emerge, p4merge, etc) instead.
A cool tip in doing merge conflict resolution in Git is that if you run git diff , it will show you both sides of the conflict and how you’ve resolved it as shown here. Now it’s time to mark the file as resolved. In Git we do that with git add — to tell Git the file has been resolved you have to stage it.
And now we’ve successfully resolved our merge conflict and committed the result.
In a nutshell you use git merge to combine another branch context into your current branch. It automatically figures out how to best combine the different snapshots into a new snapshot with the unique work of both.
docs book git log show commit history of a branch
So far we have been committing snapshots of your project and switching between different isolated contexts, but what if we’ve forgotten how we’ve got to where we are? Or what if we want to know how one branch differs from another? Git provides a tool that shows you all the commit messages that have lead up to the snapshot you are currently on, which is called git log .
To understand the log command, you have to understand what information is stored when you run the git commit command to store a snapshot. In addition to the manifest of files and commit message and information about the person who committed it, Git also stores the commit that you based this snapshot on. That is, if you clone a project, what was the snapshot that you modified to get to the snapshot that you saved? This is helpful to give context to how the project got to where it is and allows Git to figure out who changed what. If Git has the snapshot you save and the one you based it on, then it can automatically figure out what you changed. The commit that a new commit was based on is called the «parent».
To see a chronological list of the parents of any branch, you can run git log when you are in that branch. For example, if we run git log in the Hello World project that we have been working on in this section, we’ll see all the commit messages that we’ve done.
To see a more compact version of the same history, we can use the —oneline option.
What this is telling us is that this is the history of the development of this project. If the commit messages are descriptive, this can inform us as to what all changes have been applied or have influenced the current state of the snapshot and thus what is in it.
We can also use it to see when the history was branched and merged with the very helpful —graph option. Here is the same command but with the topology graph turned on:
Now we can more clearly see when effort diverged and then was merged back together. This is very nice for seeing what has happened or what changes are applied, but it is also incredibly useful for managing your branches. Let’s create a new branch, do some work in it and then switch back and do some work in our master branch, then see how the log command can help us figure out what is happening on each.
First we’ll create a new branch to add the Erlang programming language Hello World example — we want to do this in a branch so that we don’t muddy up our stable branch with code that may not work for a while so we can cleanly switch in and out of it.
Since we’re having fun playing in functional programming languages we get caught up in it and also add a Haskell example program while still in the branch named ‘erlang’.
Finally, we decide that we want to change the class name of our Ruby program back to the way it was. So, we can go back to the master branch and change that and we decide to just commit it directly in the master branch instead of creating another branch.
So, now say we don’t work on the project for a while, we have other things to do. When we come back we want to know what the ‘erlang’ branch is all about and where we’ve left off on the master branch. Just by looking at the branch name, we can’t know that we made Haskell changes in there, but using git log we easily can. If you give Git a branch name, it will show you just the commits that are «reachable» in the history of that branch, that is the commits that influenced the final snapshot.
This way, it’s pretty easy to see that we have Haskell code included in the branch (highlighted in the output). What is even cooler is that we can easily tell Git that we only are interested in the commits that are reachable in one branch that are not reachable in another, in other words which commits are unique to a branch in comparison to another.
In this case if we are interested in merging in the ‘erlang’ branch we want to see what commits are going to effect our snapshot when we do that merge. The way we tell Git that is by putting a ^ in front of the branch that we don’t want to see. For instance, if we want to see the commits that are in the ‘erlang’ branch that are not in the ‘master’ branch, we can do erlang ^master , or vice versa. Note that the Windows command-line treats ^ as a special character, in which case you’ll need to surround ^master in quotes.
This gives us a nice, simple branch management tool. It allows us to easily see what commits are unique to which branches so we know what we’re missing and what we would be merging in if we were to do a merge.
In a nutshell you use git log to list out the commit history or list of changes people have made that have lead to the snapshot at the tip of the branch. This allows you to see how the project in that context got to the state that it is currently in.
docs book git tag tag a point in history as important
If you get to a point that is important and you want to forever remember that specific commit snapshot, you can tag it with git tag . The tag command will basically put a permanent bookmark at a specific commit so you can use it to compare to other commits in the future. This is often done when you cut a release or ship something.
Let’s say we want to release our Hello World project as version «1.0». We can tag the last commit ( HEAD ) as «v1.0» by running git tag -a v1.0 . The -a means «make an annotated tag», which allows you to add a tag message to it, which is what you almost always want to do. Running this without the -a works too, but it doesn’t record when it was tagged, who tagged it, or let you add a tag message. It’s recommended you always create annotated tags.
When you run the git tag -a command, Git will open your editor and have you write a tag message, just like you would write a commit message.
Now, notice when we run git log —decorate , we can see our tag there.
If we do more commits, the tag will stay right at that commit, so we have that specific snapshot tagged forever and can always compare future snapshots to it.
We don’t have to tag the commit that we’re on, however. If we forgot to tag a commit that we released, we can retroactively tag it by running the same command, but with the commit SHA at the end. For example, say we had released commit 558151a (several commits back) but forgot to tag it at the time. We can just tag it now:
Tags pointing to objects tracked from branch heads will be automatically downloaded when you fetch from a remote repository. However, tags that aren’t reachable from branch heads will be skipped. If you want to make sure all tags are always included, you must include the —tags option.
If you just want a single tag, use git fetch <remote> tag <tag-name> .
By default, tags are not included when you push to a remote repository. In order to explicitly update these you must include the —tags option when using git push .
In a nutshell you use git tag to mark a commit or point in your repo as important. This also allows you to refer to that commit with a more memorable reference than a SHA.
Git: советы новичкам – часть 2
Во второй части нашего пособия для новичков в Git мы рассказываем об управлении ветками, особенностях их слияния, а также о принципах работы указателей. Первую статью вы можете прочитать по ссылке.
Глава 8. Ветки
Концепция веток не так проста. Представьте, что вам нужно внести множество изменений в файлы вашего рабочего каталога, но эта работа экспериментальная – не факт, что всё получится хорошо. Вы бы не хотели, чтобы ваши изменения увидели другие сотрудники до тех пор, пока работа не будет закончена. Может просто ничего не коммитить до тех пор? Это плохой вариант. Мы уже знаем, что частые коммиты и пуши – залог сохранности вашей работы, а также возможность посмотреть историю изменений. К счастью, в Git есть механизм веток, который позволит нам коммитить и пушить, но не мешать другим сотрудникам.
Перед началом экспериментальных изменений вы должны создать ветку. У ветки есть имя. Пусть она будет называться my test work. Теперь все ваши коммиты будут идти именно туда. До этого они шли в основную ветку разработки – будем называть её master. Другими словами, раньше вы были в ветке master (хоть и не знали этого), а сейчас переключились на ветку my test work. Это выглядит так:
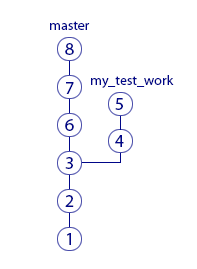
После коммита «3» создана ветка и ваши новые коммиты «4»и «5» пошли в неё. А ваши коллеги остались в ветке master, поэтому их новые коммиты «6», «7», «8» добавляются в ветку master. История перестала быть линейной.
На что это повлияло? Сотрудники теперь не видят изменений файлов, которые вы делаете. А вы не видите их изменений в своих рабочих файлах. Хотя историю изменений в ветке master вы все-таки посмотреть можете.
Итак, теперь вы сможете никому не мешая сделать свою экспериментальную работу. Если её результаты вас не устроит, вы просто переключитесь на ветку master (на её последний коммит – на рисунке это коммит «8»). В момент переключения файлы в вашей рабочей папке станут такими же, как у ваших коллег, а ваши изменения исчезнут. Теперь ваша рабочая копия стала слепком из коммита «8». По картинке видно, что в нём нет ваших изменений, сделанных в ветке my test work.
Глава 9. Слияние веток
Теперь мы знаем, что каждый может создать ветки и работать независимо. Можно по очереди работать то в одной ветке, то в другой – переключаясь между ними. Ветки переключает команда checkout.
Ветки используются не только для временной независимой работы. Часто мы одновременную готовим несколько версий игры. Например, одна версия уже почти готова к публикации и программисты вносят в неё последние исправления. В то же время гейм-дизайнеры уже занимаются следующим обновлением. Им нельзя работать в предыдущей версии потому, что:
- Их изменения не должны появиться в текущей версии;
- Любые изменения могут что-то сломать, поэтому перед публикацией версии нужно вносить в неё как можно меньше изменений.

Здесь коммит «8» – это специальный коммит, который называется merge-commit. Когда мы выполняем команду merge, система сама создает этот коммит. В нём объединены изменения ваших коллег из коммитов «5», «6», «7», а также ваша работа из коммитов «3», «4».
Изменения из коммитов «1» и «2» объединять не нужно, ведь они были сделаны до создания ветки. А значит изначально были и в ветке master, и в ветке my test work.
Команда merge ничего не посылает в origin. Единственный ее результат – это merge-commit (на рисунке кружок с номером 8), который появится у вас на компьютере. Его нужно запушить, как и ваши обычные коммиты. Только после этого merge-commit отправится на origin – тогда коллеги увидят результат вашей работы, сделав pull.
Глава 10. Несколько мержей из ветки А в ветку В
В предыдущей главе мы узнали, как сделать новую ветку, поработать в ней и залить изменения в главную ветку. На картинке после объединения ветки слились вместе. Означает ли это, что в ветке my test work теперь работать нельзя – она ведь уже объединилась с master? Нет, вы можете продолжать коммитить в ветку my test work и периодически мержить в главную ветку. Как это выглядит:
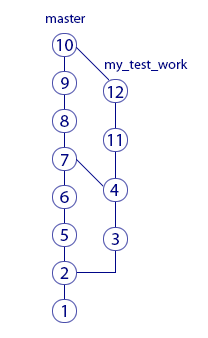
Обратите внимание, что отрезки соединяющие ветки не горизонтальные – так показано, из какой ветки в какую был мерж. В этой ситуации было два мержа и оба из правой ветки в левую. Результатом первого объединения стал merge-commit «7», а второго – merge-commit «10». Поскольку мерж происходит из правой ветки в левую, то, например, в слепке «8» есть изменения, которые были сделаны в коммите «3». А вот в слепке «11» нет изменений, которые были сделаны в коммите «5». Убедитесь, что вы понимаете причину этого. Если нет, перечитайте главы о ветках ещё раз.
Глава 11. Мерж между ветками в обе стороны
В предыдущем примере мы всё время мержили из ветки my test work в ветку master. Можно ли мержить в обратную сторону и есть ли в этом смысл? Можно. Есть.
Если вы долго работаете в своей ветке, рекомендуется периодически делать мерж в неё из главной ветки. Это необходимо, чтобы вы работали с актуальными версиями файлов, которые меняют другие люди. Как это выглядит:
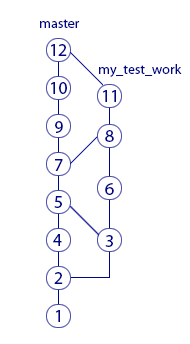
Здесь два мержа из ветки my test work в ветку master и один мерж в обратную сторону. Результатом обратного объединения стал merge-commit «8». Благодаря ему, например, слепок коммита «11» содержит изменения из коммита «7». А вот изменений из коммита «9» в слепке «11» уже нет, ведь этот коммит был сделан после мержа.
Глава 12. Коммиты и их хеши
Как Git различает коммиты? На картинках мы для простоты помечали их порядковыми номерами. На самом деле каждый коммит в Git обозначается вот такой строкой:
Это «названия» коммитов, которые Git автоматически даёт им при создании. Вообще, такие строки принято называть «хеш». У каждого коммита хеш разный. Если вы хотите кому-то сообщить об определённом коммите, можно отправить человеку хеш этого коммита. Зная хеш, он сможет найти этот коммит (если это ваш коммит, то, конечно, его надо сначала запушить).
Глава 13. Ветки и указатели
Сейчас мы немного углубимся в то, как Git хранит информацию о ветках. Вроде бы внутреннее устройство Git нас не должно волновать, но это позволит намного лучше понимать, что происходит при выполнении операций в Git. А вы, в свою очередь, сможете избежать ряда ошибок.
Познакомимся с концепцией «указателя». В упрощённом виде указатель состоит из своего названия и хеша. Вот пример указателя:
Тут вы скажете: «master – знакомое имя! У нас так называлась главная рабочая ветка». И это совпадение не случайно. Git использует указатели для обозначения веток. Идея простая: если нужна новая ветка, Git создаёт новый указатель, даёт ему имя ветки и записывает в него хеш последнего (самого свежего) коммита ветки. Ветка создана!
Благодаря хешу в указателе можно сказать, что указатель ссылается или «указывает» на последний коммит ветки. Этого достаточно Git’у, чтобы выполнять все операции над ветками. То есть, никакой другой информации о том, какие коммиты принадлежат какой ветке Git не хранит. Вот так всё минималистично.
На каждую ветку есть свой указатель. Когда в ветку добавляется очередной коммит, хеш в указателе меняется, чтобы снова «указывать» на последний коммит. Это можно представить, как сдвигание указателя ветки на последний коммит с предпоследнего.
Если вы просите Git переключиться на другую ветку (команда checkout), ему достаточно найти указатель с именем этой ветки и взять из него хеш последнего коммита. Теперь Git знает, как должны выглядеть файлы вашего рабочего каталога (как слепок этого коммита). Git приводит файлы к такому виду – и переключение на ветку произошло.
Если вы не совсем поняли идею указателей и то, как они связаны с ветками, перечитайте главу ещё раз. В Git многое завязано на указатели, поэтому важно чётко понимать механику их работы. К счастью, она совсем не сложная, просто немного необычная. Нужно лишь привыкнуть.
Глава 14. Указатель head
Итак, мы знаем, что указатели – это такие штуки, у которых есть имя, и они ссылаются на определенный коммит (хранят его хеш). Мы знаем, что при необходимости новой ветки, Git создаёт указатель на ее последний коммит и двигает его вперед при каждом новом коммите.
Указатели используются не только для веток. Есть особый указатель head. Он указывает на коммит, который выступает состоянием вашего рабочего каталога. Поняли идею? Вот пример:
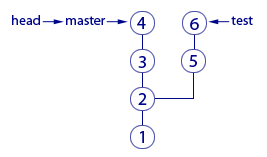
Здесь мы видим две ветки, которые представлены двумя указателями: master и test. Мы находимся в ветке master и файлы нашего рабочего каталога соответствуют слепку коммита «4». Откуда мы это знаем? Из того, что указатель head указывает на коммит «4». Точнее, он указывает на указатель master, который указывает на коммит «4». Почему бы не указывать напрямую на коммит «4»? Зачем такой финт с указанием на указатель? Так Git обозначает, что сейчас мы находимся в ветке master.
Мы можем поставить указатель head на любой коммит – для этого есть команда checkout. Вспомним, что на какой коммит показывает head, в таком состоянии и будут файлы в рабочем каталоге (это свойство указателя head). Поэтому переставляя указатель head на другой коммит, мы тем самым заставим Git поменять файлы нашего рабочего каталога. Это может потребоваться, например, чтобы откатиться на старую версию рабочих файлов и посмотреть, как там всё было. А потом можно вернуться назад к последнему коммиту ветки master (checkout master). Если же сделаем checkout test (см. картинку), то head будет указывать на указатель test, который указывает на последний коммит ветки test. Файлы в рабочем каталоге поменяются на слепок «6». Так мы переключились на ветку test.
Подытожим. Перестановка особого указателя head приводит к тому, что файлы рабочего каталога меняются на слепок этого коммита. Но только тогда, когда head указывает на указатель какой-то ветки, Git считает, что мы находимся в этой ветке.
А что происходит, если head указывает на какой-то коммит напрямую (хранит его хеш)? Это состояние называется detached head. В него можно переключиться на время, чтобы посмотреть, как выглядели файлы рабочего каталога на одном из коммитов в прошлом.
Переключение (как между ветками, так и между обычными коммитами) выполняется командой checkout.
Глава 15. Указатель origin/master
Раз удалённый репозиторий (origin) такой же, как наш, значит там тоже есть свои указатели веток? Верно. Например, есть свой указатель master, который ссылается на самый свежий коммит в этой ветке.
Интересно, что когда мы забираем свежие коммиты из origin командой pull, то вместе с коммитами скачиваются и копии указателей оттуда. Чтобы не путать наш указатель master и тот, который скачался с origin, второй из них отображается у нас, как origin/master. Нужно понимать, что origin/master не показывает текущее состояние указателя master в удаленном репозитории, это лишь его копия на момент выполнения команд fetch или pull.
master и origin/master могут указывать на разные коммиты. Станет понятнее, если посмотреть на картинку:

Здесь показана ситуация, когда мы забрали свежие коммиты (командой pull), сделали два новых коммита, но ещё не сделали push. В итоге наш локальный master показывает на последний коммит. А origin/master – это последнее известное нам состояние указателя из удалённого репозитория. Поэтому он и «отстал».
После команды push два верхних коммита уйдут в origin и логично, что origin/master подвинется вверх и тоже будет указывать на наш последний коммит, как и master.
А может ли быть так, что origin/master будет наоборот выше, а master ниже? Может. Вот как это получается. Команда pull забирает свежие коммиты и сразу же помещает их в рабочий каталог. Сразу после команды pull оба указателя origin/master и master будут указывать на один и тот же последний коммит. Но есть ещё команда fetch. Она, как и pull, скачивает последние коммиты из origin, но не торопится обновлять рабочий каталог. Графически это выглядит так (если у вас нет незапушенных коммитов):
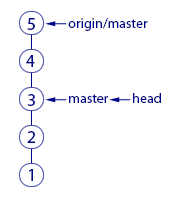
До команды fetch указатель master показывал на коммит «3» и это был последний коммит в нашем репозитории. После fetch скачались два новых коммита «4» и «5». В удалённом репозитории указатель master, очевидно, указывал на коммит «5». Этот указатель скачался нам вместе с коммитами и теперь мы его видим как origin/master, указывающий на «5». Всё логично.
Зачем может потребоваться fetch? Например, вы не готовы менять состояние рабочего каталога, а просто хотите поглядеть, чего там накоммитили ваши коллеги? Вы делаете fetch и изучаете их коммиты. Когда будете готовы, делаете команду merge. Она применит скачанные ранее коммиты к вашему рабочему каталогу.
Поскольку в этом простом примере у вас не было незапушенных коммитов, то команде merge объединять ничего не придётся. Она просто подвинет указатели master и head – теперь они будут показывать на коммит «5». Как и origin/master.
Вы можете заметить, что ничего по-настоящему сложного в описанных механиках нет. Есть лишь множество деталей, в которых приходится кропотливо разбираться. Но Git – он такой.
В финальной части статьи мы расскажем о том, откуда взялась ветка, почему push выдаёт ошибку и что такое rebase. И, конечно, подведем итоги.
In Git, what is the difference between origin/master vs origin master?
origin/master is an entity (since it is not a physical branch) representing the state of the master branch on the remote origin .
origin master is the branch master on the remote origin .
So we have these:
- origin/master ( A representation or a pointer to the remote branch)
- master — (actual branch)
- <Your_local_branch> (actual branch)
- <Your_local_branch2> (actual branch)
- <Your_local_branch3> (actual branch)
Example (in local branch master ):
(Note: When this question was originally posted, «master» was the default name for branches in Git. Since «main» is now the default name, this answer has been updated to use «main», in the hope that this will be more natural for people new to Git.)
There are actually three things here: origin main is two separate things, and origin/main is one thing. Three things total.
- main is a local branch
- origin/main is a remote tracking branch (which is a local copy of the branch named «main» on the remote named «origin»)
- origin is a remote
Is origin/main remote?
The origin/main branch is local! Any time you fetch from origin , origin/main will get updated. However, origin/main can be out of date, and it’s even possible that main no longer exists on origin . You can use the —prune option ( -p ) with git fetch to automatically delete remote tracking branches if the branch they track is deleted.
The origin/main branch is not a reference or pointer to the main branch on origin . It is a local copy.
Example: pull in two steps
Since origin/main is a branch, you can merge it. Here’s a pull in two steps:
Step one, fetch main from the remote origin . The main branch on origin will be fetched and the local copy will be named origin/main .
Then you merge origin/main into main .
Then you can push your new changes in main back to origin :
More examples
You can fetch multiple branches by name.
You can merge multiple branches.
Can you use a different name?
My local branch doesn’t have to be named main if I don’t want to. It doesn’t have to have the same name as the remote branch! Let’s say I want to name my branch alice , but still have it track origin/main :
I can do that easily enough:
You can see that the local branch is named alice , but the remote branch is named main , and the local copy is origin/main . This is totally OK! It might be a bit confusing, but maybe you already have a different branch named main , and you need to switch to a different branch to work on a different change.
origin/master is the remote master branch
Usually after doing a git fetch origin to bring all the changes from the server, you would do a git rebase origin/master , to rebase your changes and move the branch to the latest index. Here, origin/master is referring to the remote branch, because you are basically telling GIT to rebase the origin/master branch onto the current branch.
You would use origin master when pushing, for example. git push origin master is simply telling GIT to push to the remote repository the local master branch.
В чем разница между origin / master и origin master в Git?
Я знаю, происхождение — это термин для удаленного репозитория, а мастер — это ветвь там.
Я намеренно опускаю здесь «контекст» и надеюсь, что ответ не должен зависеть от контекста. Итак, в чем разница между origin / master и origin master в командной строке git. Есть ли однозначный способ понять, когда использовать origin / master , а когда мне следует использовать origin master ?
7 ответов
( Примечание. Когда этот вопрос был первоначально опубликован, «master» было именем по умолчанию для веток в Git. Поскольку «main» теперь является именем по умолчанию, в этом ответе теперь используется «main», в надежде, что это будет более естественно для людей, плохо знакомых с Git.)
На самом деле здесь три вещи: origin main — это две разные вещи, а origin/main — это одна вещь. Всего три вещи.
- main — местное отделение
- origin/main — это удаленная ветвь отслеживания (которая является локальной копией ветки с именем «main» на удаленном компьютере с именем «origin»)
- origin — это удаленный
Источник / главный удаленный?
Филиал origin/main местный! Каждый раз, когда вы выполняете загрузку из origin , origin/main обновляется. Однако origin/main может быть устаревшим, и даже возможно, что main больше не существует на origin . Вы можете использовать опцию —prune ( -p ) с git fetch для автоматического удаления ветвей удаленного отслеживания, если ветвь, которую они отслеживают, удалена.
Ветвь origin/main не является не ссылкой или указателем на ветвь main на origin . Это местная копия.
Пример: тянуть за два шага
Поскольку origin/main является ветвью, вы можете объединить его. Вот два шага:
Шаг первый: загрузите main с пульта origin . Будет получена ветвь main на origin , а локальная копия получит имя origin/main .
Затем вы объединяете origin/main в main .
Затем вы можете отправить свои новые изменения в main обратно в origin :
Еще примеры
Вы можете получить несколько веток по имени .
Вы можете объединить несколько веток .
Вы можете использовать другое имя?
Мое местное отделение не обязательно называть main , если я не хочу. Его имя не обязательно должно совпадать с именем удаленной ветки! Допустим, я хочу назвать свою ветку alice , но по-прежнему отслеживаю origin/main :
Я могу это сделать достаточно легко:
Вы можете видеть, что локальная ветвь называется alice , а удаленная ветка называется main , а локальная копия — origin/main . Это совершенно нормально! Это может немного сбить с толку, но, возможно, у вас уже есть другая ветка с именем main , и вам нужно переключиться на другую ветку, чтобы работать с другим изменением.
origin/master — это объект (поскольку это не физическая ветвь), представляющий состояние ветки master на удаленном origin .
origin master — это ветка master на удаленном origin .
Итак, у нас есть это:
- origin / master (представление или указатель на удаленную ветку)
- master — ( фактическая ветка )
- ( фактическая ветвь )
- ( фактическая ветвь )
- ( фактическая ветвь )
Пример (в местном филиале master ):
origin/master — это удаленная ветка master
Обычно после выполнения git fetch origin для переноса всех изменений с сервера вы выполняете git rebase origin/master , чтобы перебазировать свои изменения и переместить ветку в последний индекс. Здесь origin/master относится к удаленной ветке, потому что вы, по сути, говорите GIT переустановить ветвь origin/master на текущую ветвь.
Например, вы можете использовать origin master при нажатии. git push origin master просто указывает GIT отправить в удаленный репозиторий локальную ветвь master .
Origin — это имя удаленного URL-адреса git. Ниже может быть еще много примеров пультов.
Что касается origin / master (пример bangalore / master), это указатель на «master» коммит на сайте bangalore . Вы видите это в своем клоне.
Возможно, удаленный бангалор продвинулся дальше, так как вы выполнили «выборку» или «извлечение».
Учитывая тот факт, что вы можете переключиться на origin/master (хотя и в отключенном состоянии) при отключенном сетевом кабеле, это должно быть локальное представление ветви master в origin .
Прежде чем перейти к различию, нам нужно понять, что означает origin в Git.
origin — это не что иное, как исходное имя, присвоенное удаленному репозиторию. Origin — это просто место, вот и все. В приведенном ниже примере URL-адрес репозитория является происхождением или источником достоверной информации о том, где находится ваш код.
Теперь это происхождение или источник истины для вашего репозитория может иметь ветки, включая master или development, или вы называете это.
Теперь, взяв происхождение в контексте, мы можем легко понять следующие вещи.
- origin master : я являюсь основной веткой, находящейся в удаленном репозитории, который называется (origin).
Что произойдет, если я наберу git pull origin master ?.
Это обновит мою локальную главную ветку (на моем локальном компьютере), и все изменения будут доступны в удаленной главной ветке (т.е.
Теперь я хотел бы, чтобы мои изменения были объединены с моей локальной главной веткой, как я могу этого добиться?
git merge origin / master
Это обновит мою локальную главную ветку с моими изменениями. Причина наличия origin / master — это просто соглашение об именах, которое вы могли бы назвать своей локальной основной веткой origin / master или abcd. Таким образом, вы могли бы назвать свою локальную ветку вместо origin / master, чтобы просто master, а команда для git была бы git merge master .
Как мне обновить удаленную главную ветку со всеми локальными изменениями?